How science builds, uses and studies generative AI
A screened OpenAlex corpus of generative-AI research since 2020, classified facet by facet with validated LLM coding.
Problem
Generative-AI papers are usually counted by keyword, which mixes papers that build models with papers that only mention ChatGPT. There is no reliable picture of how the balance of building, using, evaluating and debating GenAI has shifted since 2022.
Approach
Harvested an OpenAlex corpus with GenAI concept and tool terms (2020 onward), screened every title and abstract with LLMs, and wrote a codebook for each classification facet, starting with GenAI's role in the paper, tested against hand-coded records.
Result
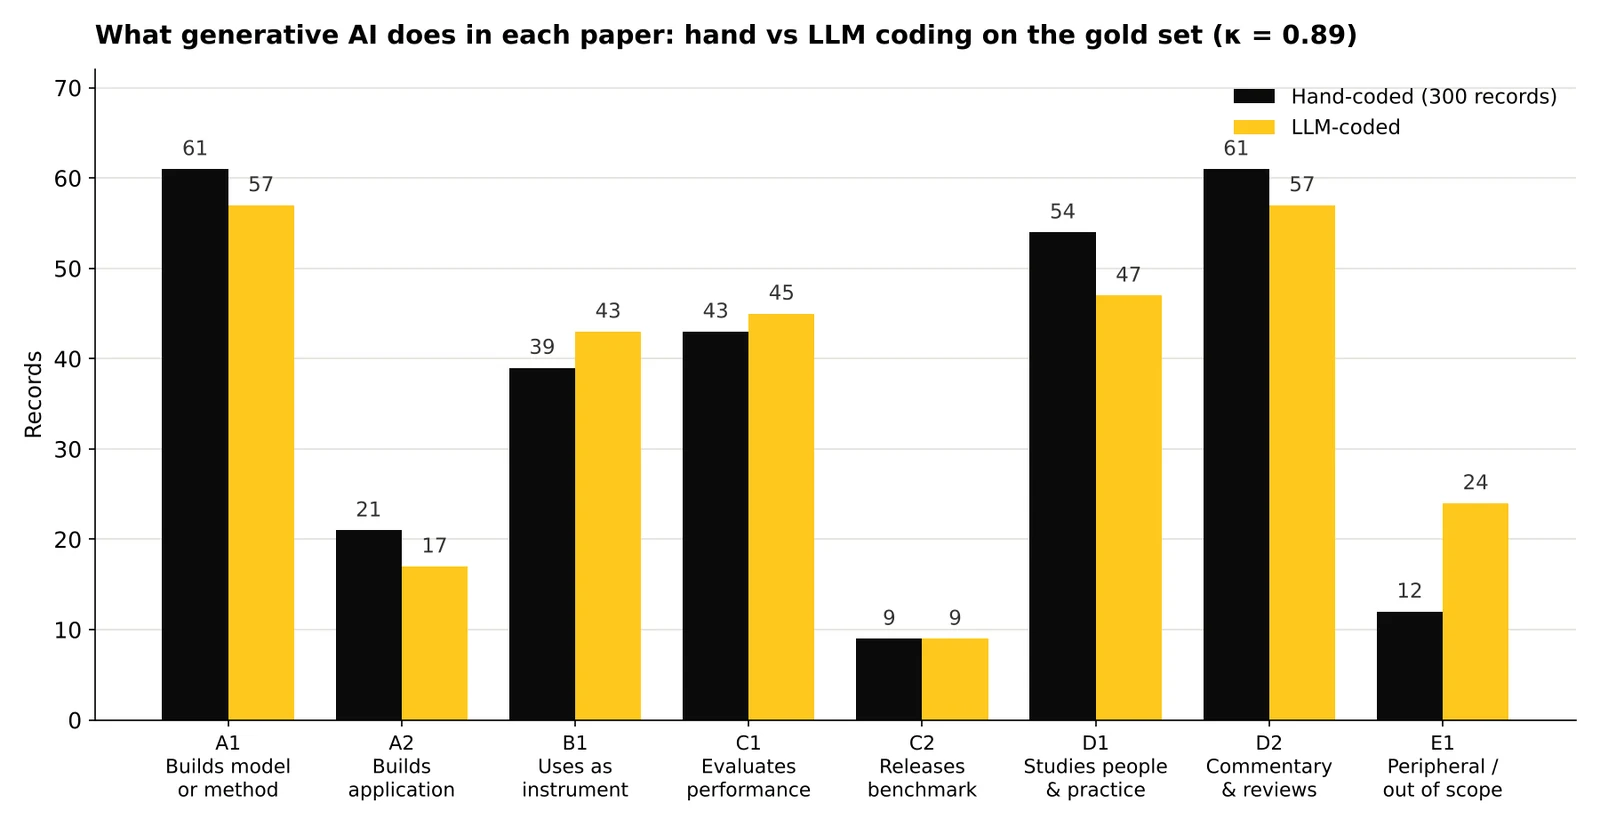
Facet 1, GenAI's role, agrees with 300 blind hand-coded records at κ 0.89 (91% agreement). More facets, articles on CognosX Insights and a public dashboard are in progress.
My role
Lead, through CognosX: corpus design, LLM screening and classification pipeline, facet codebooks, hand-coded gold standards and analysis.
Outputs
Screened corpus; facet codebooks; validated gold sets; forthcoming articles and dashboard